


Microsoft's New Surface PCs Make a Bigger Bet on Running AI Locally
By Jim McMahonon 10/08/2026 |
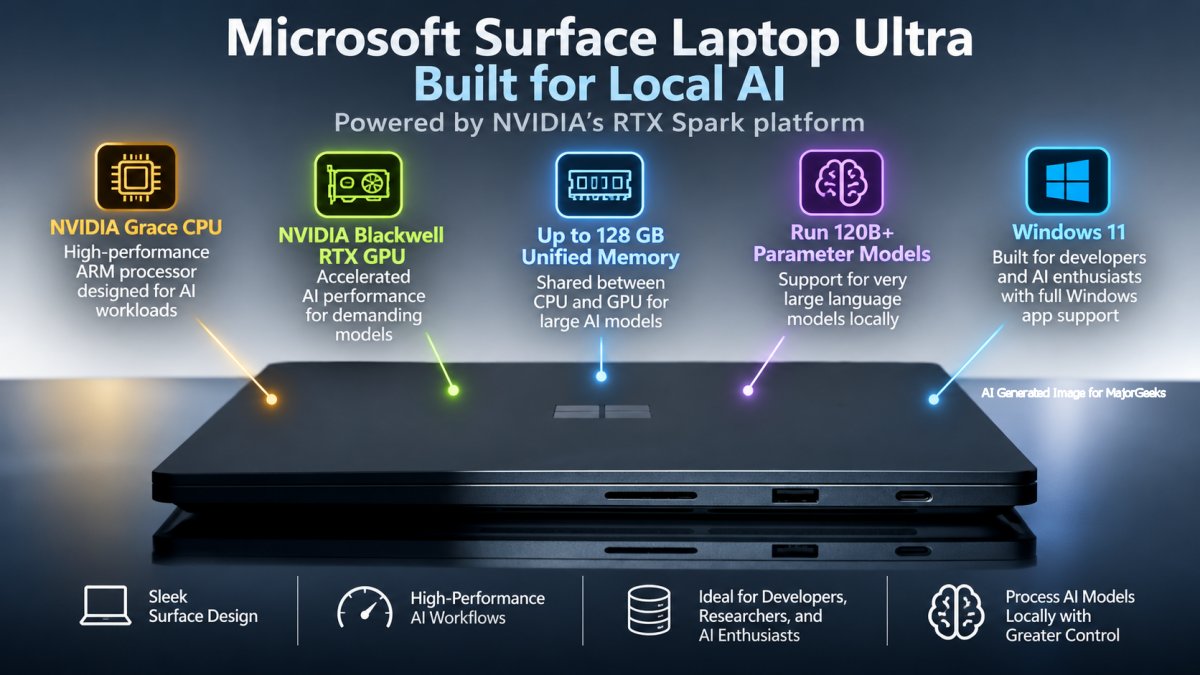
Microsoft opened preorders on October 7 for two new Surface computers built around NVIDIA's RTX Spark platform. The Surface Laptop Ultra starts at $2,599, with availability beginning October 16. The Surface RTX Spark Dev Box costs $5,999 and begins shipping in November.
At those prices, you might assume Microsoft is building expensive computers for people who use Copilot all day. But the more interesting audience may be developers, enthusiasts, and anyone experimenting with local AI tools like Ollama or other front end or agents.
These machines aren't just about asking an AI chatbot questions. They're designed to handle much more AI processing directly on your own hardware, potentially including large language models that would overwhelm a typical PC.
Why Ollama Users Might Be Interested
If you've experimented with Ollama, you already know that running AI locally can be surprisingly useful. You can download models, ask questions, generate code, summarize documents, and experiment without relying on a cloud chatbot for every request.
The catch is hardware. Smaller models can run reasonably well on ordinary computers, but larger models require considerably more memory and processing power. A graphics card with 8 GB or 12 GB of VRAM can become a limitation quickly.
Microsoft's Surface announcement describes configurations with up to 128 GB of unified memory and support for running models exceeding 120 billion parameters locally.
That's a significant amount of memory for a personal computer. Instead of being limited by the dedicated VRAM on a conventional graphics card, these systems share memory between the CPU and GPU.
That doesn't mean all 128 GB is available to the GPU, or that every large model will run quickly. But it potentially opens the door to experimenting with models that simply wouldn't fit into the memory of many consumer graphics cards.
What About Microsoft Copilot?
Here's where the marketing can get confusing.
Most everyday Microsoft Copilot features rely on cloud-based AI services. You don't need a $2,599 laptop or a $5,999 development box to ask Copilot questions, summarize text, or get help writing an email.
Local AI is different. When you run a model locally the actual processing can happen on your computer. Once the model is downloaded and properly configured, many tasks can run without an internet connection.
That gives you more control over the models you use, how you configure them, and what information you process locally. This is sup[er important if you are wworking with files that you do not wanted shared publicly, or having the Big Cloud AI models train on your data. It can also eliminate per-request cloud API charges for workloads you run entirely on your own hardware.
Of course, you're paying for the hardware and electricity instead. Whether that saves money depends on how often you use it.
There's One Important Catch: Software Compatibility
Ok, before users start reaching for their wallets, there's something worth checking.
NVIDIA's RTX Spark platform combines a Grace CPU with a Blackwell RTX GPU. The Grace processor uses ARM architecture, making this different from a conventional Intel or AMD Windows computer equipped with a GeForce graphics card.
That matters because running Ollama isn't simply about having enough memory. The software, operating system, GPU drivers, and acceleration libraries all need to work together.
Ollama supports NVIDIA GPU acceleration on compatible systems, but that doesn't automatically guarantee full GPU acceleration on every new Grace/Blackwell Windows configuration.
Until compatibility and independent benchmarks are confirmed for these specific Surface machines, buyers shouldn't assume their favorite models will run at full speed. Will, they? Probably, but verify that before yo drop the cash.
The same caution applies to other local AI software, including LM Studio Oggabooga and llama.cpp.
Memory Is Only Half the Story
A computer capable of loading a massive AI model isn't necessarily capable of running it at a speed you'll enjoy. Memory capacity determines how much model data can fit. Memory bandwidth and processing performance help determine how quickly the computer can generate responses.
Quantization also matters. It reduces the memory required to run a model, although the trade-offs depend on the model and settings.
For someone running a small 7B or 8B model, an existing gaming PC with a decent NVIDIA graphics card might already be perfectly adequate.
For someone experimenting with 70B models, larger context windows, or multiple local AI workloads, additional memory becomes much more interesting.
The important comparison isn't simply how many billions of parameters a computer supports. It's how well the particular model you want to use actually performs.
Who Should Consider These Machines?
Ok, these thing look pretty. I would love to have one at my desk every day, but they aren't cheap.
For everyday browsing, office work, occasional Copilot questions, and general Windows use, these computers are probably overkill.
For developers building AI applications, people testing different local language models, and enthusiasts who regularly push beyond the memory limits of consumer graphics cards, the story changes.
The Surface RTX Spark Dev Box in particular looks more like a specialized development workstation than a typical home computer.
That doesn't automatically make it a good deal. At $5,999, buyers should compare it with conventional GPU workstations, existing hardware, and cloud computing costs before committing.
The Geek Verdict
The most interesting thing about Microsoft's new Surface AI hardware isn't Copilot. It's the possibility of running much larger AI models directly on a personal computer.
For people already experimenting with Ollama, that could be a much more compelling reason to pay attention than another AI feature built into Windows.
But there's a big difference between impressive hardware specifications and proven real-world performance. Until we see confirmed Ollama compatibility, GPU acceleration, and independent benchmarks, these machines are promising rather than proven.
If you're curious about local AI, you certainly don't need to spend thousands of dollars to get started. Download Ollama or LM Studio, try a smaller model on your existing computer, and see what it can do on your PC and if that sort of thing would fit into your daily world.
You might discover that the hardware you already own is good enough. And if it isn't, at least you'll know exactly what you need before spending workstation money.

|
Jim McMahon
Jim McMahon, aka Corporal Punishment, is the founder of MajorGeeks.com. He has spent decades testing software, troubleshooting Windows, and helping users cut through the nonsense. He loves real freeware, hates bloatware, and runs on caffeine, sarcasm, and questionable choices. |
